Imagine a restaurant where the cook must reread the health manual, memorize the menu, and review every recipe before making one coffee. Technically correct. Operationally, a wonderful way to create a queue.
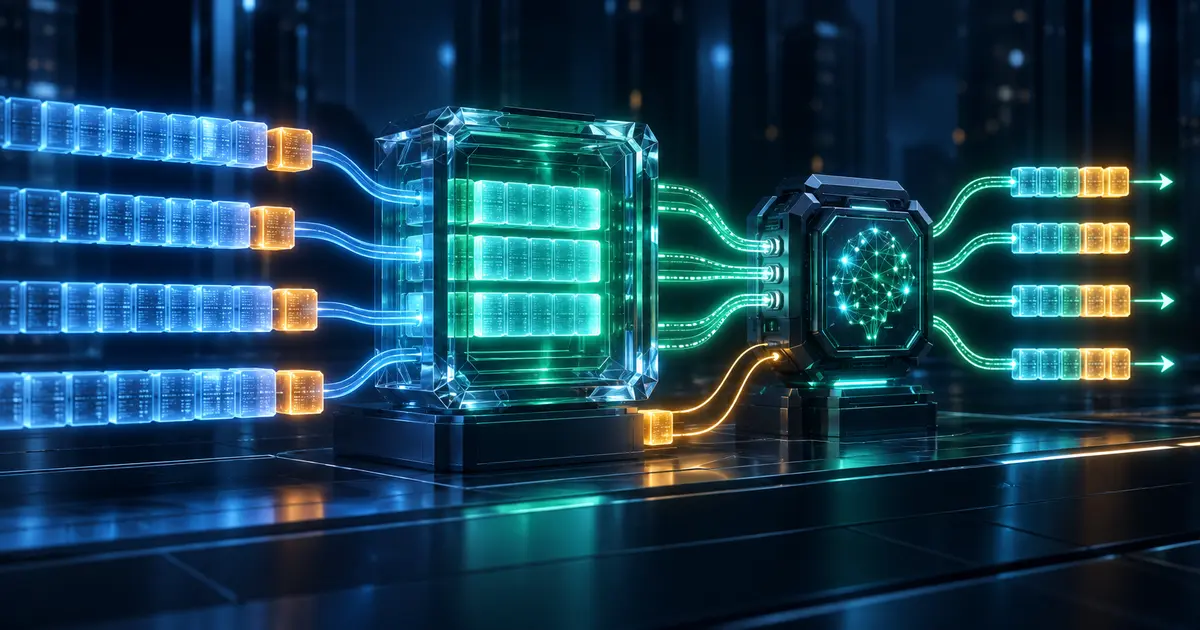
LLM applications often do something similar. Each call repeats system instructions, tool definitions, examples, and documents. Prompt caching reuses the work of processing this stable section. The coffee is still made fresh; the manual simply does not need to be rediscovered for every cup.
It is not a response cache
During inference, a model first processes the input — the prefill phase — and then generates the output token by token. During prefill it computes internal attention states, commonly called KV states or tensors.
According to the OpenAI documentation, caching preserves those states for a reusable prefix; it does not simply store a ready-made answer. A new question must still be processed, and the model generates a new output.
| Technique | What it reuses | Can the result change? |
|---|---|---|
| response cache | the complete output | usually no |
| semantic cache | an answer to a similar question | depends on policy |
| prompt caching | processing of an identical prefix | yes, generation is new |
Prompt caching mainly improves input cost and time to first token. It does not make the model smarter, and it cannot magically accelerate a long response dominated by output generation.
The most profitable adjective is “stable”
Prompt caches operate on prefixes. Shared content must come first and remain identical; variable content comes later.
A typical order is:
- tool definitions;
- system instructions and policies;
- fixed examples;
- shared documents or context;
- history and the variable question.
Anthropic evaluates the prefix in tools, system, and messages order up to the cache breakpoint. Its Claude documentation recommends static content first and supports explicit breakpoints. OpenAI provides implicit caching on compatible models and explicit controls on recent models. Gemini enables implicit caching by default for 2.5 and newer models and follows the same principle: place large shared content first and send requests with similar prefixes near one another in time.
The pattern matters more than vendor syntax:
[ tools + rules + stable examples ][ variable data and question ]
Putting a changing date, random ID, or reordered tool list at the beginning is like changing the lock and complaining that yesterday's key stopped working.
A cache hit does not happen out of kindness
The rendered prefix must match. Small changes before a cache breakpoint can invalidate everything after that point. Model configuration and tool schemas may also be part of the cache identity, depending on the provider.
Retention varies. As of September 2026, Anthropic documents five minutes by default, refreshed when used, and an optional one-hour lifetime at extra cost. OpenAI documents in-memory retention typically between five and ten minutes of inactivity, potentially up to one hour, with extended options on compatible models. These are current product characteristics, not laws of physics; check the documentation for the model you use.
Minimum token thresholds also apply. A short prompt may not qualify. If the whole instruction fits on a napkin, the caching strategy may become the system's most expensive component.
The bill has separate buckets
A useful cost model is:
new input + cache write + cache read + output
Anthropic's current documentation prices a five-minute write at 1.25 times base input, a one-hour write at twice base input, and a read normally at 0.1 times base input, with model-specific exceptions. There is a break-even point: paying for a write makes sense only when the prefix will be reused.
Consider an illustrative 10,000-token prefix plus a 500-token variable question. With one request, the extra write may not pay off. With 100 requests reusing the prefix, processing those 10,000 tokens from scratch 100 times becomes an excellent loyalty program — for the provider.
An AWS vendor benchmark for Amazon Bedrock reports latency reductions of up to 85% and cost reductions of up to 90% for compatible models and workloads. The words “up to” deserve a spotlight: these are vendor-observed upper bounds that depend on size, repetition, timing, and the ratio between input and output. The same material presents a workload with only 2,000 static tokens and substantial dynamic content as a limited-benefit case.
A design that usually works
For a technical-support agent, content might be divided into:
- stable by version: policy, tone, response schema, and tools;
- stable by hour: a large catalog or manual;
- dynamic by session: customer history;
- dynamic by call: the new question and tool results.
Separating content by rate of change makes it possible to choose sensible breakpoints and retention. A new tool version should deliberately change the prefix. Gradual deployment can use consistent versions so contracts are not mixed. Personalized content belongs after the shared section, improving both cache reuse and governance.
Measure before celebrating
Four indicators tell the story:
- share of tokens read from cache, not merely requests with any hit;
- time to first token with cold and warm caches;
- effective cost per completed task, including writes and outputs;
- invalidation rate, segmented by version, tool, and route.
Compare P50 and P95 distributions using representative traffic. Two consecutive calls prove that the API works; they do not prove that your application keeps prefixes stable on deployment day.
Prompt caching is not authorization, tenant isolation, or a retention policy. Review the provider's data controls and never depend on caching to hide information. It optimizes computation; it does not replace security architecture.
The main point
Static prompt caching is less about pressing a button and more about designing context order. Stable tools, rules, and examples go first. Volatile data goes last. Metrics determine whether the design delivered a benefit.
Done well, the model receives no less information and returns no stale answer. It simply stops rereading the entire manual to discover, for the hundredth time, where the coffee machine is.
References
- OpenAI. Prompt caching, accessed September 2026.
- Anthropic. Prompt caching, accessed September 2026.
- Google. Context caching — Gemini API, accessed September 2026.
- AWS. Effectively use prompt caching on Amazon Bedrock, 2025.